French startup Kog targets 10x LLM inference speed boost on standard GPUs
CEO Gaël Delalleau says Kog Inference Engine can deliver 30x faster processing, with a September milestone set to drive Series A fundraising
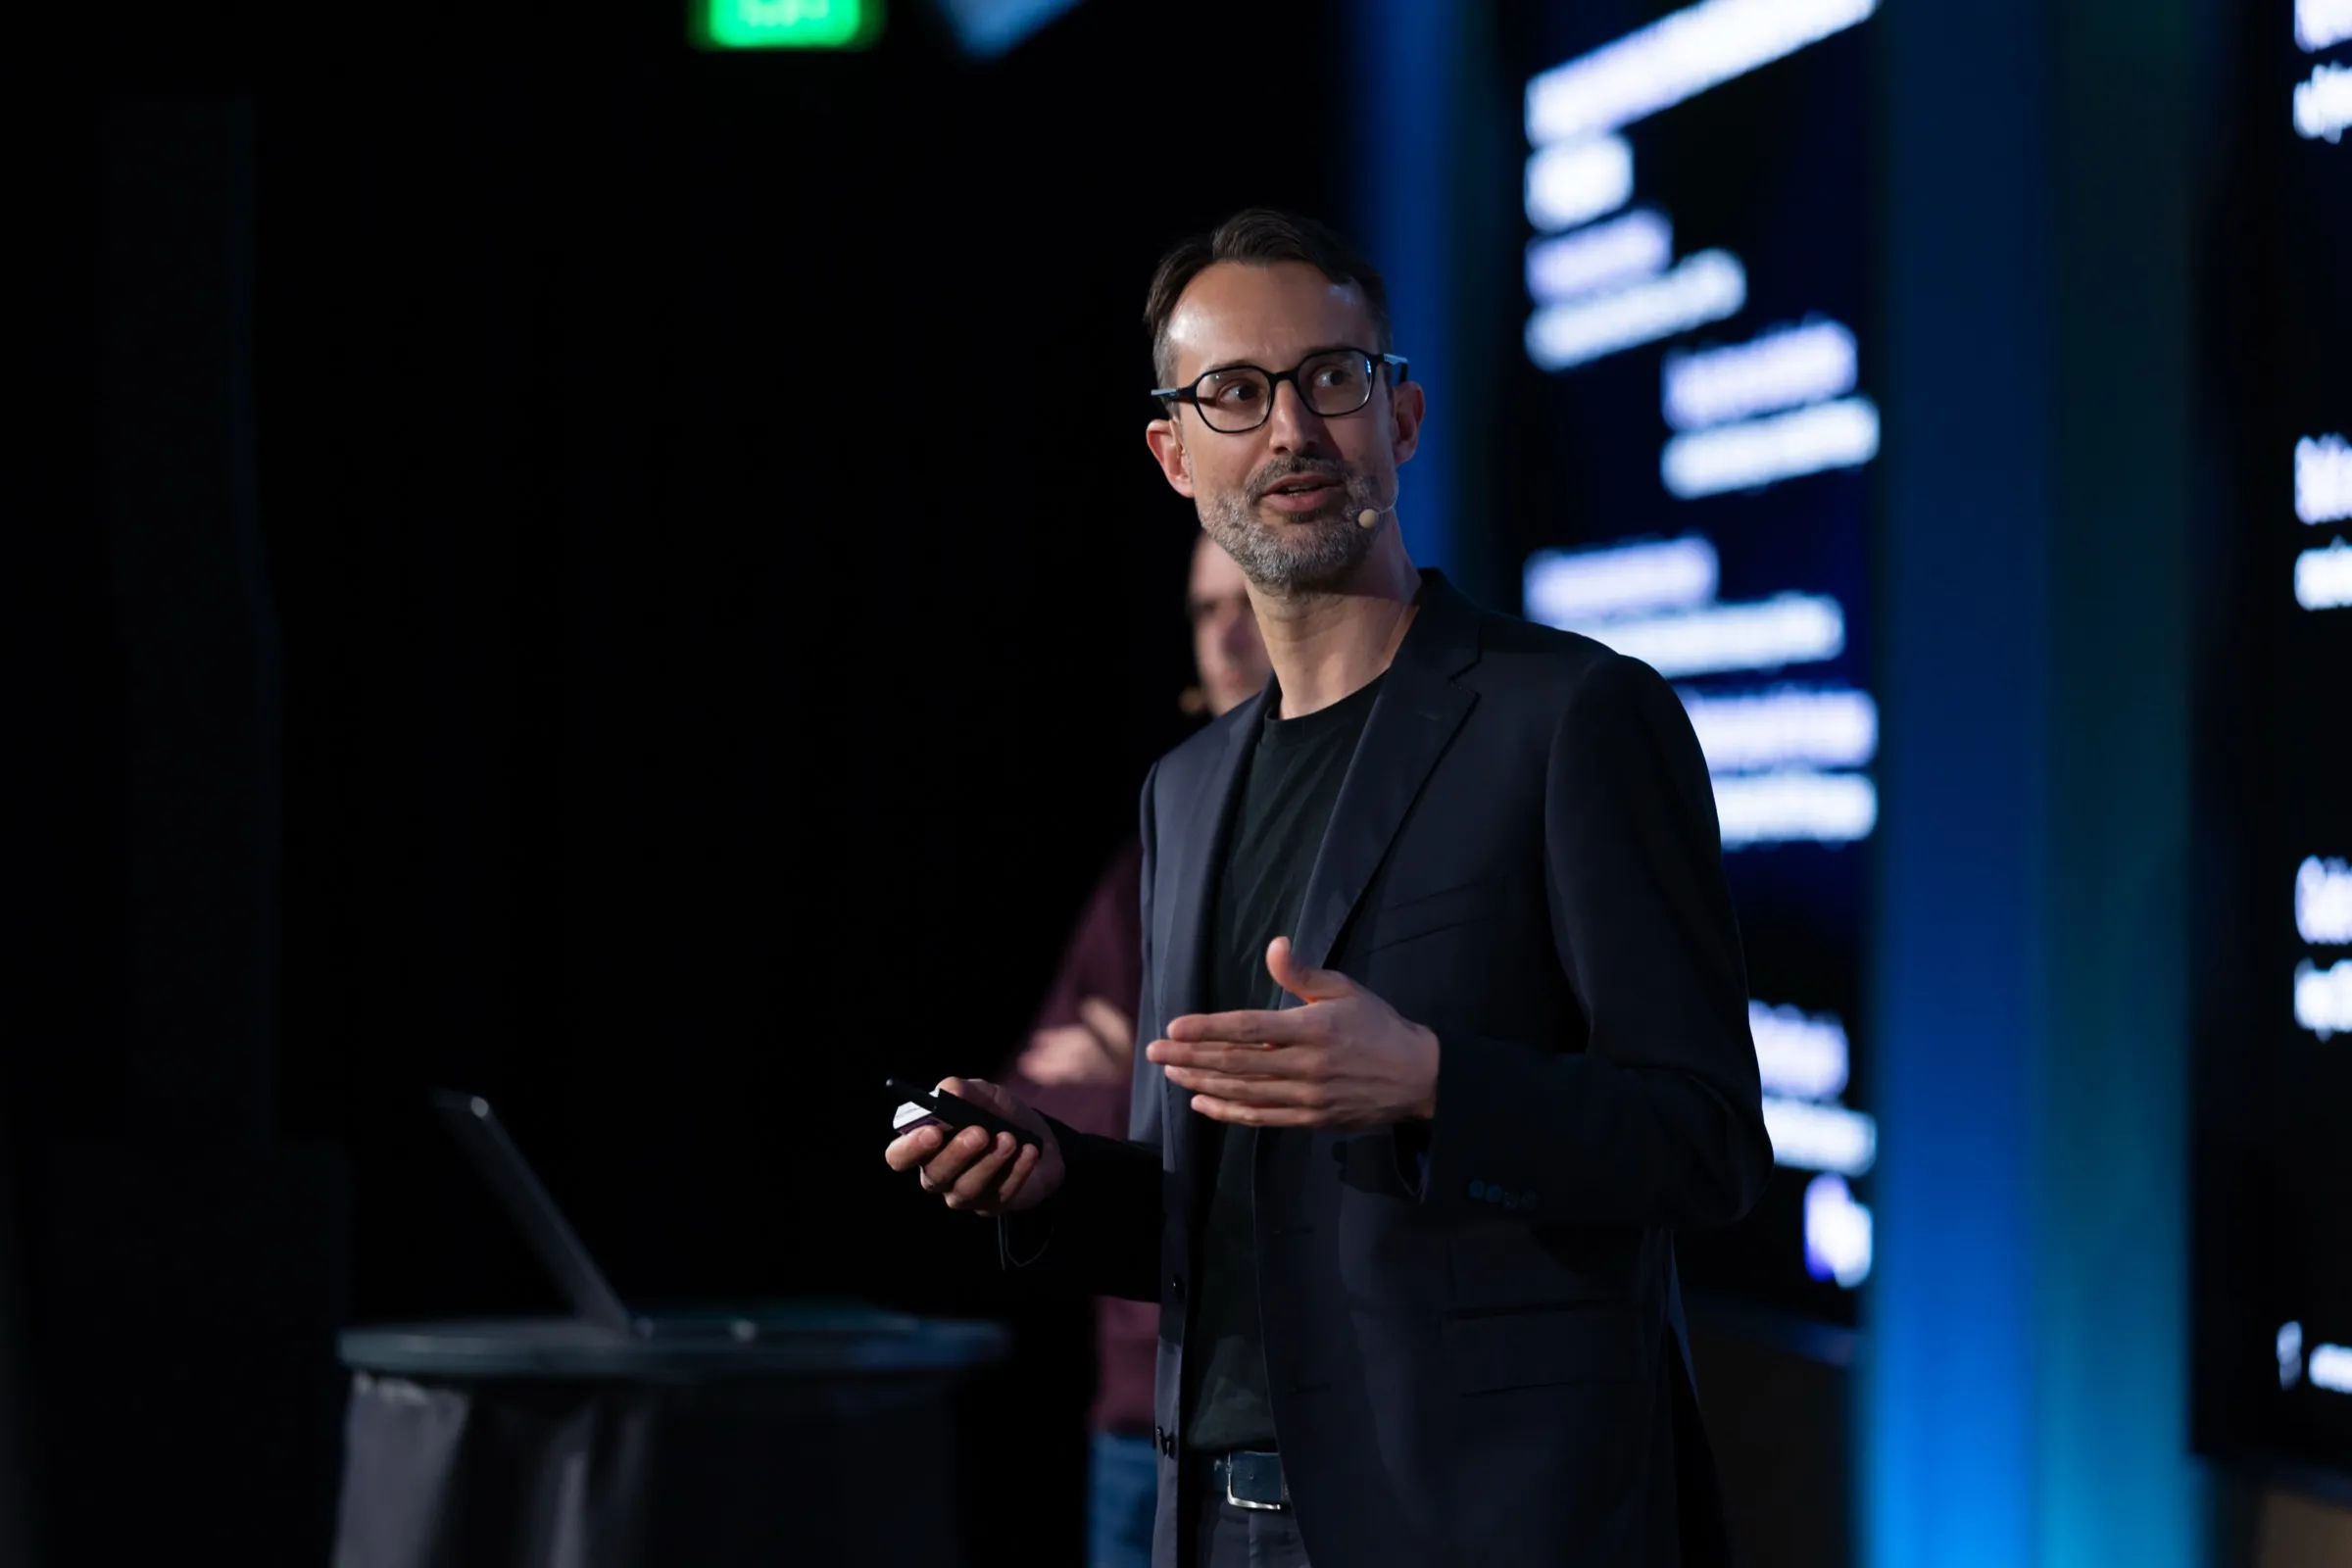
French startup Kog is developing software designed to significantly accelerate large language model inference on conventional datacentre graphics processing units, including AMD MI300X and NVIDIA H200 models. The company claims its Kog Inference Engine (KIE) can achieve up to 30 times faster processing by optimising hardware at a low level, targeting high-value use cases such as software engineering and agentic workflows.
The startup has secured seed funding led by Varsity VC and is backed by Scaleway, France’s Bpifrance, and the French Tech 2030 program. CEO Gaël Delalleau announced plans to demonstrate 10x speed improvements on major models by September, a milestone intended to validate customer traction and support the company’s Series A fundraising efforts.
Kog’s initial technology preview in May demonstrated 3,000 tokens per second using the open-sourced Laneformer 2B model, a small model with approximately 2 billion parameters. Following this demonstration, the company received 200 tangible business leads. However, early feedback indicated that prospective customers were not prepared to fine-tune small models, prompting Kog to pivot its focus toward accelerating larger language models to meet market demand.
Delalleau, who holds a background in solid-state physics and offensive cybersecurity, argues that the perception of GPUs being poorly suited for agentic workflows is a misconception. He states that newer GPUs possess substantial memory bandwidth that remains largely untapped. Kog’s approach involves deep-level GPU engineering, a methodology Delalleau compares to the work of Stanford University’s Hazy Research lab, rather than the hardware-agnostic strategies employed by competitors such as ZML.
The company’s technical strategy is informed by Delalleau’s experience as a four-time finalist at DEF CON’s Capture The Flag tournament, which he says instilled a mindset of reverse-engineering systems down to the assembly language level. With a team of 11 people, Kog dedicates weeks or months to researching each new GPU architecture, a process that limits the number of chips the firm can support in the short term.
In the longer term, Kog intends to integrate its methodology into agent-based pipelines to expand its hardware compatibility. The startup operates within a broader European push to build independent AI capabilities, a trend that may provide sovereignty tailwinds for French firms.